TL;DR

Get smart everyday buys delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
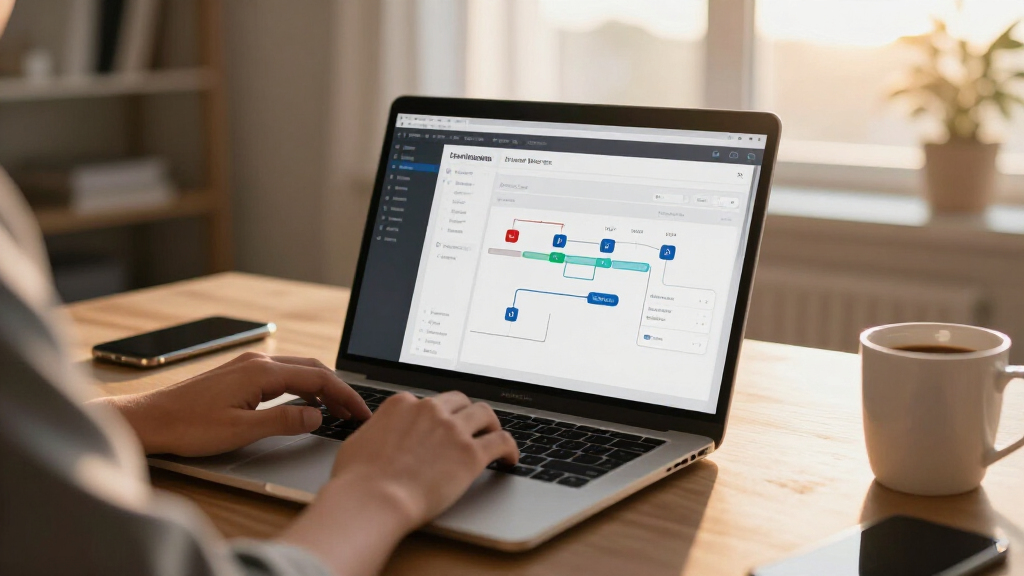
A new approach to local AI document processing pipelines emphasizes modularity, robustness, and data privacy. This architecture enables organizations to run AI models entirely on-premises, improving control and compliance.
Why Modular, Local Pipelines Are a Game-Changer for AI Deployment
This architecture offers organizations greater control over their AI workflows, reducing reliance on external cloud providers and mitigating data privacy concerns. It simplifies maintenance, upgrades, and debugging by isolating components and standardizing interfaces. For regulated industries, the detailed provenance and audit trail are critical for compliance. Overall, this approach paves the way for more secure, reliable, and adaptable AI systems that can be tailored to specific operational needs, making AI deployment more sustainable and trustworthy.Products Worth Considering

FLEXISPOT 42-Inch Electric Standing Desk Converter

Dell P2725H 27-Inch Full HD Monitor

Brother QL-800 High-Speed Professional Thermal Label Printer
As an affiliate, we earn on qualifying purchases.
Evolution Toward Self-Contained AI Document Pipelines
Recent developments in AI have highlighted the need for local, on-premises solutions that prioritize data privacy and operational control. Over the past week, industry leaders demonstrated capabilities such as a 3B parameter model reading 40 pages in one pass and the importance of local inference under new transparency regulations. These trends underscore a shift away from monolithic, cloud-dependent systems toward modular, maintainable pipelines. The architecture builds on prior work in OCR, structured extraction, and database-backed queuing, consolidating these into a cohesive, version-controlled framework designed for production environments.“This reference architecture embodies the principles of simplicity, modularity, and data integrity, enabling organizations to run robust AI pipelines entirely on-premises.”
— Thorsten Meyer
Unresolved Questions About Deployment and Scalability
It is not yet clear how well this architecture performs at scale across diverse enterprise environments or how it handles complex multi-language or multi-format documents. Additionally, the ease of integrating new models and components in existing workflows remains to be tested in varied operational contexts.Next Steps for Adoption and Standardization
Organizations are expected to adopt pilot implementations of this architecture, with ongoing refinements based on real-world feedback. Industry groups and standards bodies may begin formalizing best practices for local AI pipelines, emphasizing modularity, provenance, and compliance. Further research will likely focus on optimizing component interoperability and scaling strategies for large datasets and diverse document types.Key Questions
What are the main benefits of a local AI document pipeline?
Running AI pipelines locally improves data privacy, reduces dependency on external cloud providers, and enhances control over operational workflows. It also simplifies compliance with regulations and allows for easier maintenance and upgrades.
How does this architecture support model swapping?
The pipeline components are designed with a standardized CLI interface, allowing models to be replaced or upgraded via simple configuration changes without affecting the rest of the system.
Is this architecture suitable for large-scale enterprise deployment?
While promising, its scalability and performance at enterprise scale are still being tested. The architecture’s reliance on PostgreSQL and simple job management suggests good potential, but real-world validation is ongoing.
What are the regulatory implications of using such a local pipeline?
By keeping all data processing on-premises and maintaining detailed provenance records, organizations can better meet compliance requirements, especially in regulated sectors like finance and healthcare.
What challenges might organizations face when adopting this architecture?
Challenges include integrating existing systems, ensuring performance at scale, and maintaining the pipeline as models and data formats evolve. Ongoing development and community feedback will be critical.
Source: ThorstenMeyerAI.com